Dec 28, 2022

How to Create an AWS MySQL RDS Read Replica

Why?

Read Replica provides you extra read-only power, so you can direct your heavy load SELECT (OLAP) queries to the read replica, while the main RDS cluster can serve your critical OLTP transactions.

How?

To create a MySQL read replica in Amazon Web Services (AWS) using Amazon Relational Database Service (RDS), you can follow these steps:

  1. Sign in to the AWS Management Console and navigate to the RDS dashboard.
  2. In the navigation pane, click on the "Instances" menu item.
  3. Select the instance that you want to use as the source for the read replica.
  4. From the "Actions" dropdown menu, select "Create read replica".
  5. In the "Create Read Replica" dialogue box that appears, you can specify the following options:
  • The instance identifier for the read replica. This should be unique within your AWS account.
  • The instance class for the read replica. You can choose from a range of instance sizes based on your performance and capacity needs.
  • The storage type and size for the read replica. You can choose between magnetic and SSD storage, and specify the size in gigabytes.
  • The availability zone for the read replica. This determines the geographical region where the read replica will be located.
  • The security group and VPC for the read replica. You can use the same security group and VPC as the source instance, or choose different ones.
  1. Click "Create read replica" to create the read replica. It will be created as a new RDS instance, and will be automatically replicating data from the source instance.

You can monitor the progress of the read replica creation process by checking the "Status" column on the RDS dashboard. When the status of the read replica changes to "available", it is ready to use.

Keep in mind that read replicas are designed to be used for read-only workloads, and you cannot write to them directly. Any writes to the source instance will be replicated to the read replica, but you cannot write directly to the read replica.

Keep Performing, Moshe Kaplan

Dec 3, 2022

Monitoring Dashboard Principles for AWS Serverless System

A monitoring dashboard for a serverless system would typically include information about the health and performance of the system, such as the number of requests being handled, the average response time, and any errors or issues that are occurring. The specific metrics and information included on a monitoring dashboard can vary depending on the specific system and the needs of the users. Some common metrics that might be included on a monitoring dashboard for a serverless system include:

  1. Request count: The number of requests being handled by the system.
  2. Error rate: The percentage of requests that are resulting in errors.
  3. Latency: The average time it takes for a request to be processed.
  4. CPU and memory usage: The amount of CPU and memory resources being used by the system.
  5. Throughput: The amount of data being processed by the system.
  6. Scalability: Information about how the system is scaling up or down in response to changes in workload.

These are just some examples of the types of information that might be included on a monitoring dashboard for a serverless system. The exact metrics and information displayed on the dashboard will depend on the specific needs of the system and the users. 

Keep Performing,

Moshe Kaplan

Nov 6, 2022

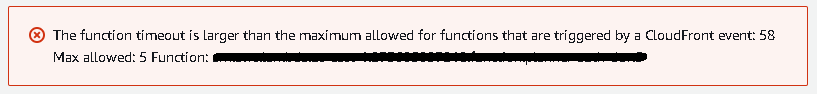
Why you get 503 with your AWS Lambda@Edge?

 The short answer: Lambda@Edge is limited to a 5 seconds timeout

The reason: If you configured your lambda to a larger timeout (let's say 58 sec), when you deploy it to Lambda@edge, AWS would automatically adjust the number to a lower number (for us it was 1 second).

The solution is simple: You should not configure your Lambda functions that will be deployed to Lambda@Edge for more than 5 seconds.

How Trace it?

1. You get a 503 when you try to login a Cognito secured site for example with "The Lambda function associated with the CloudFront distribution is invalid or doesn't have the required permissions"


2. When you go to the CloudWatch to examine the logs, you find out, that some function end after 1000 ms.

Keep Performing,
Moshe Kaplan


Oct 17, 2022

How to Enable AWS OpenSearch Slow Logs?

The first step to solving a data performance issue is tracing the slow queries.

OpenSearch support two types of queries:

  1. Indexing: write queries
  2. Searching: read queries
You will be able to find out what is your performance bottleneck in the AWS cluster health dashboard. If you will find out that indexing is your bottleneck, you may enable the indexing slow log according to the AWS docs.
If you find out that your bottleneck is the search queries, you may use the following:

Get The list of index:
curl -X PUT "https://YOUR-CLUSTER-NAME.eu-west-1.es.amazonaws.com/_cat/indices?pretty"

Enable the slow log on the relevant indexes:

curl -X PUT "https://YOUR-CLUSTER-NAME.eu-west-1.es.amazonaws.com/YOUR-INDEX-NAME/_settings?pretty" -H 'Content-Type: application/json' -d'
{
  "search": {
    "slowlog": {
      "threshold": {
        "query": {
          "warn": "15s",
          "trace": "750ms",
          "debug": "3s",
          "info": "10s"
        }
      },
      "level": "TRACE"
    }
  }
}'

Where query defines the thresholds, and the level the minimal threshold that will be logged to the file.

After enabling the slow query log, you may be able to find the link to the log itself in the AWS cluster logs tab.

Bottom Line
After analyzing the slow log, you may be able to get some light on your performance spots.

Keep Performing,

Sep 6, 2022

The Data Analyst Guide: How to Connect Your MongoDB Database

  1. Install MongoDB Compass
  2. Connect to your MongoDB Cluster
  3. Run an aggregation query
You can find the detailed process in our video

Keep Performing,

Aug 31, 2022

How did We Manage to Integrate Two Large Data based Services? or How to Query Large Number of Records from the MySQL database?

A common case in enterprise systems and micro-services-based architecture is the need to sync data between 2 systems or services.

For example, a billing system in a telco may need updated status regarding the customers' plan.

Common Solutions:

1. A Low latency Service

A common approach might be having a scaleable, low latency service that will be able to respond to status queries within 1ms. This can be achieved using golang based service and a Redis backend for example.

2. A PubSub architecture

In this approach, we will update the billing system w/ recent updates and will need to assume the billing database is updated with the latest updates. This is a very efficient method, yet it is prone to discrepancies and data drifting.

3. Batch Queries

The last method that we'll discuss in this post is having a batch query reg, "hot" subscribers, and getting back the results to the billing system. It might be less sophisticated than the other approaches, yet it is simple and less prone to load data drifting.

The Integration Patttern

The billing system would like to retrieve the status of up to 30K subscribers, in order to enrich the CDR (call data records) files.

This approach may be chosen, in order to minimize the number of calls between the two systems and to avoid data drifting.

As the number of subscribers is too large, to include in a single query, a naive solution, might be to query all the subscribers from the database and filter them at the application level.

A better solution might be using the TEMPORARY TABLE mechanism to extract only the needed subscribers from the table

Step by Step Solution

1. Insert the subscriber ids we get from the billing to a temporary table

CREATE TEMPORARY TABLE temp_billing_sps_subs_id (

   subscriber_id bigint

);

2. Add a JOIN to the current query w/ the temp table

3. Get back up to 30K records instead of 2M.

Few things to think about:

1. We may need to add a new index to match the updated queries

2. We may need to add permissions in production to create these temporary tables.

Bottom Line

It may improve query response time (fewer data to fetch from disk and return to app server) and app query time (less time to scan the 2M records and filter them).

Keep Performing,

May 9, 2022

Duplicate Your MongoDB ATLAS ReplicaSet/Cluster

Well, does a MongoDB ReplicaSet/Cluster duplication for backup or test purposes sound like an obvious task?

Think again :-)

There is no magic button or anything like that, but there are a few tools that can be used to complete this task:

Backup and Restore

Use mongodump and mongorestore to backup your current instance and restore to a new instance. To save bandwidth and minimize time, make sure you use an instance in the cloud vendor region matching your MongoDB ATLAS.

Mirroring

Use the mongomirror to migrate the data to the new cluster. Please notice the mongomirror do not copy config and permissions.

Bottom Line

I believe the backup/restore method might be best in most cases, but you can have it your way

Keep Performing 

Moshe Kaplan

Jan 12, 2022

Creating Webhooks on a MySQL Table?

If you need to create a webhook on a MySQL table, having a field that marks the last modification date of any record, can be a great start

ALTER TABLE  my_table
ADD COLUMN modified DATETIME ON UPDATE CURRENT_TIMESTAMP,
ADD INDEX IX_modified (modified);

Keep Performing,
Moshe Kaplan

Jan 1, 2022

How to Prepare Your MySQL Slave to be Promoted to Master?

 Just a few steps, but make sure you do them on peacetime, as during downtime every minute counts.

1. Enable bin log, you will need them when you will want to add new slaves to the promoted master.

log_bin                = /var/log/mysql/mysql-bin.log
expire_logs_days        = 10
max_binlog_size        = 100M
binlog_format = mixed

2. Copy Master nodes users and permissions from the Master to the Slave

MASTER> mysqldump -uUSER -p -t mysql user > /tmp/dump.sql
SLAVE> mysql -uUSER -p -D mysql < /tmp/dump.sql
SLAVE> mysql -uUSER -p -e "FLUSH PRIVILEGES;"

P.S Consider using Galera as a Multi-Master solution to avoid the need to promote a node manually. However, in some cases, such as a delayed slave or hidden one, that might be the right solution.

Keep Performing,
Moshe Kaplan

Dec 19, 2021

MongoDB DataOps: Fork, Lookup , mongostat, Custom Replication and Taking Care of Failed System

Why fork is used?

fork is the right way to make sure your MongoDB runs as a daemon. In this case, fork should be defined as true in the configuration file. If you want to run it as an interactive process. just set it to false.

How to Perform Lookup?

db.classes.aggregate( [
{ $lookup: {
  from: "members",
  localField: "enrollmentlist",
  foreignField: "name",
  as: "enrollee_info"
}}
])

mongostat and mongotop

These two great tools are provided as part of the MongoDB installation and can be used to detect the queries types and collections that most heavily affect the MongoDB performance.

Simple Backup and Restore

mongodump --out /tmp/dump/
mongorestore mongodb://127.0.0.1 /tmp/dump/

How to Reset Your MongoDB Instance?

Stop the service, remove all content from the /var/lib/mongodb directory, and start the service again:
sudo service mongod stop
sudo rm -rf /var/lib/mongodb
sudo service mongod start

Setting Custom Replication Source

MongoDB replication automatically balances between replication from the Primary (most updated values) and secondaries w/ a low networking latency to minimize WAN network usage and optimize network resources.
However, your can control this behavior and configure specific source rs.syncFrom() command. Please notice that this command result is temporary and will reset to default once mongod is restarted, connection closed between nodes or 30 sec timeout is reached.

Initiate Your Replicaset:

1. Set the replicaset name in the mongod.conf file
2. Change the bindIP to 0.0.0.0 in the config file
3. Run on the first node the rs.initiate command
rs.initiate(
   {
      _id: "rs",
      version: 1,
      members: [
         { _id: 0, host : "172.30.0.158:27017" },
         { _id: 1, host : "172.30.0.151:27017" },
         { _id: 2, host : "172.30.0.219:27017" }
      ]
   }
)

Search for Delta in the Oplog

db.oplog.rs.find({"ts":{$gt : Timestamp(1640074543, 1)}})

Upgrade from MySQL 5.6 to 8.0

Verify your system configuration to select the right package and method for installation

uname -r
> 2.6.32-696.3.2.el6.x86_64  ==> 64bit

uname -r
> Description:    CentOS release 6.9 (Final) => CentOS 6.9

Upgrade to the latest 5.6

Look for the latest MySQL 5.6 minor version and get the package:

wget https://downloads.mysql.com/archives/get/p/23/file/MySQL-5.6.51-1.el6.x86_64.rpm-bundle.tar

Remove current package
sudo service mysqld stop
sudo yum -y remove mysql-community-common-5.6.36-2.el6.x86_64

tar -xvf MySQL-5.6.51-1.el6.x86_64.rpm-bundle.tar
sudo rpm -i MySQL-client-5.6.51-1.el6.x86_64.rpm
sudo rpm -i  MySQL-server-5.6.51-1.el6.x86_64.rpm
sudo service mysql start
sudo mysql_upgrade

Upgrade to the latest 5.7
wget https://dev.mysql.com/get/Downloads/MySQL-5.7/mysql-5.7.35-1.el6.x86_64.rpm-bundle.tar
sudo service mysql stop
sudo yum -y remove MySQL-server-5.6.51-1.el6.x86_64 MySQL-client-5.6.51-1.el6.x86_64
tar -xvf mysql-5.7.35-1.el6.x86_64.rpm-bundle.tar
sudo rpm -i mysql-community-libs-5.7.35-1.el6.x86_64.rpm mysql-community-common-5.7.35-1.el6.x86_64.rpm mysql-community-client-5.7.35-1.el6.x86_64.rpm mysql-community-server-5.7.35-1.el6.x86_64.rpm
sudo service mysqld start
sudo mysql_upgrade

Upgrade to the latest 8.0
Look for latest MySQL 8.0 minor version
wget https://dev.mysql.com/get/Downloads/MySQL-8.0/mysql-8.0.26-1.el6.x86_64.rpm-bundle.tar

sudo service mysqld stop
sudo yum -y remove mysql-community-libs-5.7.35-1.el6.x86_64 mysql-community-common-5.7.35-1.el6.x86_64 mysql-community-client-5.7.35-1.el6.x86_64 mysql-community-server-5.7.35-1.el6.x86_64
tar -xvf mysql-8.0.26-1.el6.x86_64.rpm-bundle.tar
sudo rpm -i mysql-community-client-plugins-8.0.26-1.el6.x86_64.rpm mysql-community-common-8.0.26-1.el6.x86_64.rpm mysql-community-libs-8.0.26-1.el6.x86_64.rpm mysql-community-client-8.0.26-1.el6.x86_64.rpm mysql-community-server-8.0.26-1.el6.x86_64.rpm
sudo service mysqld start


Comparing SQL to MongoDB Query Syntax

#MongoDB Aggregation Pipeline

db.documents.aggregate([
{"$match": {"name": "/^asdasd/"}},
{"$group": {"_id": "$name", {"cnt": {$sum:1}}},
{"$match": {"cnt": {$gt: 3}}},
{"$lookup": {from: "meta", localField:"name", foreignField:"name", as: "meta"}}
{"$match": {"meta": {$exists: True}}},
{"$out": "debug_collection"}
]);

#SQL Syntax

SELECT *
FROM documents

SELECT *
FROM documents
WHERE name like 'asdasd%'

SELECT name, COUNT(*) AS cnt
FROM documents
WHERE name like 'asdasd%'
GROUP BY name

SELECT name, COUNT(*)
FROM documents
WHERE name like 'asdasd%'
GROUP BY name
HAVING COUNT(*) > 3

SELECT doc.*, meta.*
FROM meta INNER JOIN (
SELECT name, COUNT(*)
FROM documents
WHERE name like 'asdasd%'
GROUP BY name
HAVING COUNT(*) > 3) AS doc ON doc.name = meta.name

Dec 12, 2021

Your First MongoDB, C# and .NET Core App/My C# and MongoDB Cheat Sheet


Download .NET core SDK

Setup you project and your console project

  1. Select a folder
  2. In the command line: 
    dotnet new console -o console
    dotnet add console package MongoDB.Driver
    cd console
    code console
  3. vsoode will be opened

Create a program.cs file:
namespace HelloWorld
{
    class Program
    {
        static void Main(string[] args)
        {
            Console.WriteLine("Hello World!");
        }
    }
}

Run the code:
dotnet run


Now add a document and write it
using MongoDB.Driver;
using MongoDB.Bson;
using MongoDB.Bson.Serialization.Attributes;


namespace MongoData
{
    class Program
    {
        static void Main(string[] args)
        {
            Console.WriteLine("Hello World!");
            var mongoClient = new MongoClient("MONGODB_URL");
            var mongoDatabase = mongoClient.GetDatabase("trial_db");
            var collection = mongoDatabase.GetCollection<TrialDoc>("trial_cl");

            TrialDoc trialDoc = new TrialDoc();
            trialDoc.BookName = "123";
            collection.InsertOne(trialDoc);
            Console.WriteLine("Done!");
        }
    }

   
    public class TrialDoc
    {
        [BsonId]
        [BsonRepresentation(BsonType.ObjectId)]
        public string? Id { get; set; }

        [BsonElement("Name")]
        public string BookName { get; set; } = null!;

        public int Price { get; set; }

        public string Category { get; set; } = null!;

        public string Author { get; set; } = null!;
    }
}


Add Read Operation: Find All
            var list = collection.Find(_ => true).ToList();
            foreach (var item in list) {
                Console.WriteLine(item.BookName);
            }

Add Read Operation: Specific Record
            var single = collection.Find(x => x.BookName == "123".ToString()).FirstOrDefault();
            Console.WriteLine(single.Id);

Update the record
            collection.ReplaceOne(x => x.Id == single.Id, new TrialDoc() {Id = single.Id, BookName = "456"}, new ReplaceOptions {IsUpsert = true});

var _client = new MongoClient();
var _database = _client.GetDatabase("users");
var counters = _database.GetCollection<BsonDocument>("counters");
var counterQuery = Builders<BsonDocument>.Filter.Eq("_id", "eventId");

var findAndModifyResult = counters.FindOneAndUpdate(counterQuery,
              Builders<BsonDocument>.Update.Set("web", "testweb"));
            FilterDefinition<TrialDoc> filter =
                Builders<TrialDoc>.Filter.Eq(x => x.BookName, "123");
            ProjectionDefinition<TrialDoc> project = Builders<TrialDoc>
                .Projection.Include(x => x.BookName);

            var results = collection.Find(filter).Project(project).ToList();
            foreach (var item in results) {
                Console.WriteLine(item);
            }
Don't forget to create a full text search index first
            var results_list = collection.Find(Builders<TrialDoc>.Filter.Text("123")).ToList();
            foreach (var item in results_list) {
                Console.WriteLine(item);
            }


using MongoDB.Driver.GeoJsonObjectModel;
#Add to document
public GeoJson2DCoordinates Location { get; set; } = null!;
trialDoc.Location = new GeoJson2DCoordinates(31.11, 19.12);
var keys = Builders<BsonDocument>.IndexKeys.Geo2DSphere("Location");
await collection.Indexes.CreateOneAsync(keys);

Nov 29, 2021

How to Setup Your Development Environment for a MongoDB and .Net based Project

1. Get your MongoDB Atlas Replicaset 

2. Make sure you can access the MongoDB Atlas Replicaset using port 27017/TCP

3. Setup your desktop with the following as described in the embedded Loom:

 - Install MongoDB Compass on the desktop 

 - Install a coding environment with recent VS Code ready for .NET Core

Now when everything is ready, you start coding your project and enjoy the combined power of .NET Core and MongoDB

Keep Performing,
Moshe Kaplan

How to Setup a Free MongoDB Atlas Replicaset

 Having a MongoDB Relicaset was always simple, but with MongoDB Atlas, it is simple than ever.

In this two sessions video we'll learn:

1. How to open a MongoDB Atlas account, create a project and a new cluster (Replicaset)

2. How to verify you can connect your Replicaset


Nov 21, 2021

How to Install MongoDB Communitry Edition 5.0.4 on Ubuntu 18.04

Well it is super simple, and you can actually try the MongoDB guide or my embedded video:

I used for this task a t2.medium AWS instance with 2 burstable cores, 4GB RAM and 8GB gp2 SSD disks.

Keep Performing,

Moshe Kaplan

Sep 22, 2021

An Open Source Data Masking Solution for MySQL

Today we'll disucss the need for data masking due to privacy regulations such as GDPR that becone more and more common in the industry.

In order to deploy such a solution we'll utlize two great products:

1. Percona Server 8.0.17 that has recently introduced the data masking plugin (that is compatible w/ MySQL Enterprise one. This plugin exposes multiple functions that translate sensitive strings such as SSN and emails to masked strings.

2. ProxySQL a proxy server that supports modifying SQL queries on the fly. For example replacing SELECT ssn FROM users; with SELECT mask_ssn(ssn) FROM users;

The Percona Server will serve as our MySQL solution (you can use it as a slave instance if you need it for analyst purposes only). while the ProxySQL will serve as a Proxy that modifies SQL queries to utilize the Percona server data masking functions. You may also need to limit users access from the network to the Percona server.

Bottom Line

New times bring new products that can serve us to create novel solutions

Keep Performing,

Moshe Kaplan

Jun 9, 2021

MongoDB Monitoring Using Prometheus

If you environment is bound to Prometheus it is best we focus on this platform as a baseline.


We will need multiple aspects:

System Counters
Main metrics needed:
1. Machines CPU
2. Read and Write IOPS to disks
3. Memory utilization
4. Disk utilization
5. Incoming and outgoing network traffic

MongoDB Counters
For this task it is best to use the MongoDB exporter
There are also 3 Grafana dashboards provided that we can use to monitor the performance
MongoDB Overview;
MongoDB ReplSet;
MongoDB WiredTiger;

These will be able to provide us key indicators such as locks, replicaset status, 

MongoDB Slow Queries
It will also be wise to enable the MongoDB slow query w/ an initial limit of 100ms to gain some overview of the cluster slow queries:
db.setProfilingLevel(1,100)

Feb 10, 2021

Why 4 Nodes MongoDB Replicaset is not a Good Idea

Customer Question:

We have a 4 nodes replicaset w/ leading nodes each with different priority. From time to time, when we suffer from network issues, all the replicaset goes down.

Why is this Happens?

Since two of the nodes are a single site and the two other on two other sites, when the first site goes offline, no site can create a majority. Therefore, you must remove one of the nodes in the first site to avoid these downtimes.

Moreover, the MongoDB selects the primary node by priority. If the primary is unstable, everytime it will go offline, a secondary will be chosen w/ a possible few secondds replicaset downtime. When the high priority node goes back online, it will be selected again to primary (and causing another possible downtime).

Therefore, if there is no good reason, avoid specifing variable priorities.

How to fix It?

1. Perform the task during off peak hours

2. Remove the arbiter node by rs.remove() 

3. Verify replicaset is okay by running rs.status()

4. Modify the remaining nodes configuration:

cfg = rs.conf()

cfg.members[0].priority = 1

cfg.members[1].priority = 1

cfg.members[2].priority = 1

rs.reconfig(cfg)

5. Verify again.

Bottom Line

Keep it Simple :-)


Keep Performing,

Moshe Kaplan

Nov 16, 2020

MongoDB Review Checklist and Tools

Tools

  1. Analyze the mongostat results: https://docs.mongodb.com/manual/reference/program/mongostat/
  2. And mongotop to see query highlight https://docs.mongodb.com/manual/reference/program/mongotop/
  3. Enable slow queries: db.setProfilingLevel(1,50)
  4. Dex: to analyze slow queries: http://dex.mongolab.com/
  5. mtools to visualize the query usage https://github.com/rueckstiess/mtools
  6. System metrics: top and iostat

Checklist

  1. Usage and location of the Replica Set instances
  2. Check system resources usage: CPU and disk IOPS
  3. Check network latency, bandwidth  and Application level Read Preference and Write Concern
  4. Check mongo instances usage (mongostat)
  5. Check top slow queries (mongotop, slow queries)
  6. Check queries and command usage using 
  7. Check backup strategy
  8. Check storage engine and MongoDB version
  9. Check monitoring tools

ShareThis

Intense Debate Comments

Ratings and Recommendations